Monte Carlo CPU-GPU task scheduler
Splitting independent price-path simulations across CPU and GPU — static and dynamic schedules
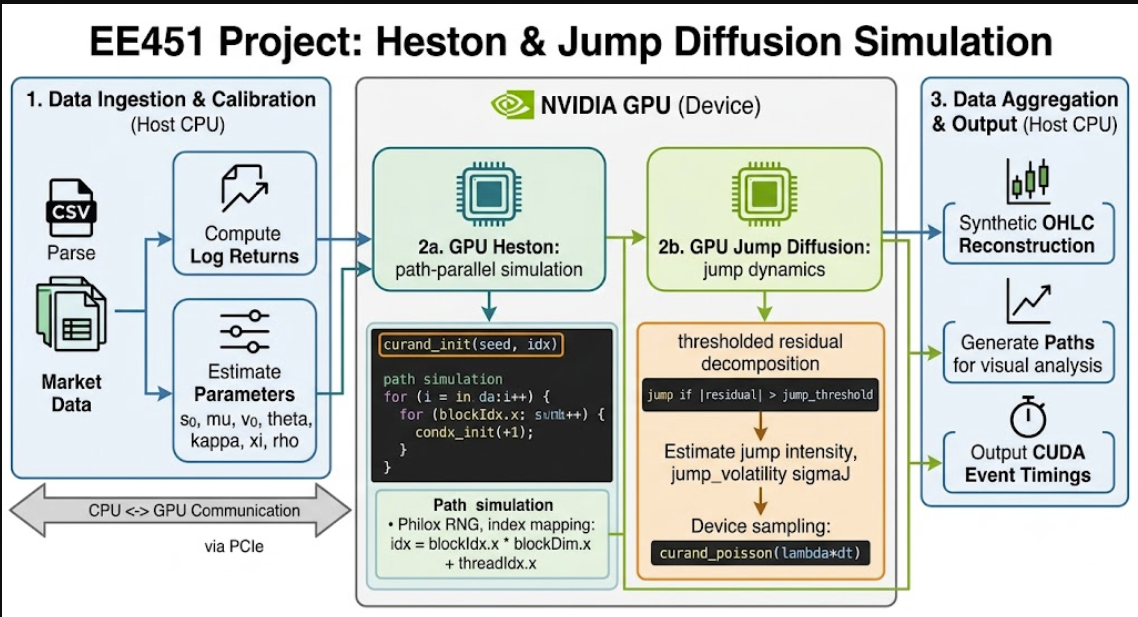
Monte Carlo CPU–GPU Task Scheduler
Parallelizing Monte Carlo path generation for stochastic FX models across CPU, GPU, and hybrid CPU+GPU schedules
Motivation
Monte Carlo simulation is a standard tool in quantitative finance: you fit a stochastic model to historical prices, then draw thousands (or millions) of independent future paths. That path loop is embarrassingly parallel — paths do not depend on each other — but it is still expensive once the time horizon and path count grow.
In trading and backtesting workflows, those paths can become synthetic OHLC bars used to stress strategies or generate scenario data. The bottleneck is almost never the fitting step or the CSV write; it is the n_paths × n_steps simulation. So the systems question is concrete:
Given a heterogeneous node with CPU cores and a GPU, how should we schedule batches of independent Monte Carlo paths to minimize wall-clock time?
This project treats that as a task-scheduling problem. A “task” is a batch of paths. The schedulers are:
- CPU-only — vectorized NumPy
- GPU-only — CUDA kernels (one thread per path)
- Hybrid — static or dynamic assignment of path batches to both devices at once
The finance models (GBM, Heston, jump diffusion) supply a realistic numerical workload. The evaluation target is runtime and scheduling efficiency, not trading PnL.
Overview
| Piece | Role |
|---|---|
| Input | FXCM USD/JPY 1-minute OHLC bars (2013) |
| Fit | Heuristic parameter estimation from log returns (host) |
| Simulate | Many independent price paths under GBM / Heston / jump diffusion |
| Schedule | CPU, GPU, or hybrid (static split / dynamic batch queue) |
| Output | Synthetic OHLC CSV + timing/params JSON |
| Platform | USC CARC Discovery via SLURM |
Pipeline:
OHLC CSV → fit params → simulate n_paths × n_steps → dress path 0 as OHLC → CSV + JSON
                │
                ├─ CPU NumPy (chunked over paths)
                ├─ CUDA kernel (1 thread = 1 path)
                └─ Hybrid orchestrator (Python + GPU subprocess)
Shared helpers live in monte_carlo/trading_model_utils.py. Model-specific CPU scripts own fit + simulation. CUDA binaries reimplement fit + sim so a SLURM GPU job can run without a Python GPU stack. Hybrid drivers (monte_carlo/hybrid/) partition paths and merge final prices only.
Data
Source: FXCM USD/JPY 1-minute bars for 2013.
| File | Content |
|---|---|
usdjpy-m1-bid-2013.csv | Bid OHLC (primary input for most jobs) |
usdjpy-m1-ask-2013.csv | Ask OHLC (used in early GBM drafts/benchmarks) |
Schema: timestamp, open, high, low, close
Example: 2013-02-01 00:00:00+00:00, 91.715, 91.715, 91.653, 91.653
The bid series has on the order of ~28k minute bars. Fitting uses log returns of close. Simulation length n_steps is either a fixed horizon (e.g. 200 steps for microbenchmarks) or the full trimmed series length for production-style Heston/hybrid runs.
Synthetic output dresses one simulated close path into OHLC (open = previous close; wicks from scaled noise) so the artifact looks like bars a backtest harness could consume. The many-path work exists for statistics and for stressing the parallel runtime.
Method
Models
GBM (baseline). Drift and volatility from log returns; closed-form per-step update. Used mainly in benchmarks/ to compare CPU vs CUDA at fixed n_steps = 200 while sweeping path counts.
Heston. Stochastic volatility with CIR variance and correlated Browns:
- Fit:
v0 = θ = Var(r); κ from lag-1 autocorrelation of squared returns; ξ from std of squared returns; default ρ = −0.2 - Step: Euler–CIR with reflection
v = max(0, …)
Jump diffusion (Merton-style). Diffusion plus Poisson jumps:
- Jumps = residuals with
|r − μ| > 2.5σ(configurable) - λ, μJ, σJ from jump residuals; diffusion σ from non-jumps
- Step: Gaussian diffusion +
Poisson(λ·dt)jumps
Fitting is heuristic, not MLE to an options surface. That is intentional: the goal is a reproducible workload with realistic per-step cost differences (Heston and jump diffusion are heavier than GBM), not pricing-grade calibration.
Parallelism strategy
| Layer | Strategy |
|---|---|
| CPU | Simulate paths in chunks (default chunk size 256): vectorized over paths, sequential in time |
| GPU | One CUDA thread = one full path; time loop on-thread |
| Launch | Default 256 threads/block; grid = ceil(n_paths / 256) |
| RNG | curand Philox (curandStatePhilox4_32_10_t), seed (base_seed, path_index) |
Paths are independent → path-level parallelism. Timesteps within a path are sequential on the worker that owns that path.
Memory and I/O choices
Full path tensors are n_paths × n_steps doubles and blow up quickly. Kernels therefore keep:
- Final price for every path (stats + hybrid merge)
- Optionally path 0 / a few sample paths (OHLC dressing, plots)
They do not ship the full path matrix back to the host. Hybrid runs merge only terminal prices from CPU and GPU.
Kernel timing uses CUDA events around the launch, separate from alloc, D2H, and CSV I/O. Hybrid reports record end-to-end wall time plus CPU/GPU phase sums.
Hybrid task scheduling
A task = a batch of paths. Two schedules:
Static. Split once (cpu_fraction default 0.35, or explicit --n-cpu / --n-gpu). Run NumPy and one GPU subprocess concurrently (ThreadPoolExecutor, 2 workers). One GPU launch → low overhead when relative throughput is known.
Dynamic. Shared remaining-path counter + lock. CPU and GPU workers claim up to --batch-cap (default 4096) until exhausted. Load-balances when relative speed is unknown; each GPU claim currently relaunches the CUDA binary as a subprocess (reload + refit + alloc), so small caps can be overhead-dominated.
Ideal parallel lower bound reported as max(t_cpu, t_gpu) (perfect overlap, no extra overhead). Throughput = n_paths / hybrid_wall_seconds.
GPU seeding is offset from CPU (seed + 1_000_003, plus batch index in dynamic mode) so pooled streams do not collide.
How it was run (USC CARC / SLURM)
All serious timings were submitted on USC CARC Discovery with SLURM. Local machines were used only for CPU smoke tests.
Environment
| Job type | Typical modules / resources |
|---|---|
| CPU synth | main partition, high mem (e.g. 96G), Python NumPy/Pandas |
| GPU Jump Diffusion | gpu partition, cuda/11.3.0, make -C monte_carlo/GPU |
| GPU Heston | gpu partition, V100 (--gres=gpu:v100:1), cuda/12.6.3, gcc/13.3.0, nvcc -arch=sm_70 |
| Hybrid Heston | Same GPU node + python/3.11.9, 4 CPUs, 16G, up to 1 hour |
CUDA Jump Diffusion builds for multiple arches (sm_60 / sm_70 / sm_80 / sm_86 + PTX) so P100/V100/A100-class nodes can reuse one binary.
Representative submissions
CPU Heston / Jump Diffusion (monte_carlo/heston_cpu_job.sl, JumpDiff_cpu_job.sl):
sbatch monte_carlo/heston_cpu_job.sl
# python heston_synth.py --input ../usdjpy-m1-bid-2013.csv --n-paths 100000 --no-plots
GPU Jump Diffusion (run_jumpdiff_gpu.slurm):
sbatch run_jumpdiff_gpu.slurm
# builds jump_diffusion_cuda, then e.g. --n-paths 1000 --n-steps 200
GPU Heston (monte_carlo/GPU/heston_job.sl):
sbatch monte_carlo/GPU/heston_job.sl 1000000
# optional 2nd arg: block size (default 256)
Hybrid Heston (monte_carlo/hybrid/hybrid_heston.sl):
cd /path/to/repo   # or flat CARC bundle
SCHEDULE=static CPU_FRACTION=0.35 N_PATHS=100000 sbatch monte_carlo/hybrid/hybrid_heston.sl
SCHEDULE=dynamic BATCH_CAP=4096 sbatch monte_carlo/hybrid/hybrid_heston.sl 500000
Each hybrid job writes hybrid_heston_<JOBID>.json with schedule, path counts, fitted params, wall time, ideal lower bound, and throughput. GPU-only runs write params JSON under reports/ (or job cwd) with kernel and host timing breakdowns.
Monitor with squeue -u $USER; inspect *.out / *.err and the JSON reports for numbers used below.
Results
Results are taken from CARC job logs and JSON timing reports (not checked into the git tree as fixed CSVs). The evaluation compares backends on the same model, same fitted params, same n_paths / n_steps, and records:
| Metric | Meaning |
|---|---|
| CPU wall / sim time | End-to-end or simulation-only NumPy time |
| GPU kernel ms | CUDA-event time around the kernel only |
| GPU host breakdown | Alloc, D2H, I/O outside the kernel |
| Hybrid wall | End-to-end static or dynamic schedule |
| Ideal lower bound | max(cpu_phase, gpu_phase) |
| Throughput | Paths per second |
What we observed (qualitative summary)
-
GPU dominates large path counts. For Heston and jump diffusion at high
n_paths(10⁵–10⁶), the CUDA path-parallel kernels finish far faster than single-process NumPy. The gap widens as path count grows because paths map cleanly onto threads and Philox RNG stays per-thread. -
Kernel time ≠ wall time. CUDA-event kernel milliseconds look much better than Python wall clocks that include fit, alloc, and CSV. Fair comparison requires stating which layer you timed. Hybrid JSON makes that explicit.
-
Static hybrid helps when the split matches device speed. With
cpu_fraction ≈ 0.35, overlapping a smaller CPU share with a larger GPU share can approach themax(cpu, gpu)bound when subprocess overhead is paid once. Measured hybrid wall sits above the ideal bound by orchestration and merge cost. -
Dynamic hybrid is overhead-sensitive. Claiming many small GPU batches re-pays CSV load + fit + process startup. At default
batch_cap = 4096, dynamic often loses to static unless relative CPU/GPU speed is badly mismatched. Larger caps reduce launch tax but weaken load balance. -
Model cost matters. Jump diffusion (variable Poisson inner loops) and Heston (two correlated Browns + CIR) stress the GPU differently than GBM. Warp divergence and per-step arithmetic change the CPU↔GPU relative throughput that static fractions should target.
-
Correctness check. Merged hybrid final-price mean/std stay consistent with CPU-only and GPU-only runs under shared fitted parameters and non-colliding seeds — evidence that scheduling changes where paths run, not what model is simulated.
Analysis and discussion
Why path-level parallelism worked. Independence across paths is the right decomposition for this workload. Timestep parallelization would require different algorithms (and more synchronization). Mapping one path to one CUDA thread keeps kernels simple and matches curand’s per-thread state model.
What “scheduling” meant here. This is not an OS scheduler and not a DAG of trading jobs. It is heterogeneous work partitioning of identical independent tasks. Static scheduling is a one-shot bin pack; dynamic scheduling is work stealing via a shared counter. Both are standard ideas from parallel computing, applied to a finance-shaped loop.
The real hybrid tradeoff. Hybrid only wins if overlap savings exceed coordination cost. Our dynamic design exposes that cost clearly because each GPU batch is a full subprocess. A production system would keep a long-lived GPU process or use CUDA streams / multi-stream queues; the educational value of the relaunch design is that overhead shows up in the numbers instead of being hidden.
What to time. Claiming “GPU is X× faster” without specifying kernel-only vs end-to-end is misleading. We report both where possible: CUDA events for the device loop, perf_counter / host clocks for wall time, and hybrid ideal bounds for overlap quality.
Workload vs product. Synthetic bars and an optional NautilusTrader Docker harness motivate the pipeline, but the scientific claim of the project is about throughput under CPU / GPU / hybrid schedules, not strategy performance.
Limitations
-
Heuristic calibration. Heston and jump-diffusion parameters are fit from returns with simple proxies, not calibrated to option markets. Fine for a systems benchmark; weak for pricing fidelity.
-
Dynamic hybrid overhead. Relaunching the CUDA binary per batch inflates dynamic-schedule cost. Results understate what a persistent GPU worker could achieve.
-
Incomplete trading integration. Synthetic CSV output is not fully wired into the NautilusTrader EMA-cross backtest (
backtest_synthetic_fx_bars.pystill leans on tutorial data). Backtesting remains a stretch goal. -
Benchmark drift. Older scripts in
benchmarks/benchmark_heston.py/benchmark_jump_diffusion.pyexpect placeholder binary names; the live CLIs areheston_gpuandjump_diffusion_cuda. Prefer those + hybrid JSON for published numbers. -
Single-node scope. Experiments use one CARC GPU node (typically one V100). No multi-GPU or multi-node scheduling.
-
Fairness caveats. CPU NumPy is one process with chunked vectorization, not a hand-tuned multi-threaded C++ CPU baseline. Absolute CPU↔GPU speedups should be read as “this Python stack vs this CUDA kernel,” not as an upper bound on CPU performance.
-
Results not frozen in-repo. Timing tables live in job output / JSON on CARC; the public tree does not pin a single canonical results CSV, so reproduced numbers can differ slightly by node type and module versions.
Takeaways
- Monte Carlo path generation is a clean EE451-style parallel workload with a finance motivation.
- GPU path-parallel kernels win at scale; hybrid scheduling only helps when the split matches device speeds and overhead stays small.
- Static hybrid is the practical default in this codebase; dynamic teaches load balance — and why process-per-batch is expensive.
- Measure the layer you claim to optimize: kernel events, host wall time, and hybrid overlap tell different stories.